
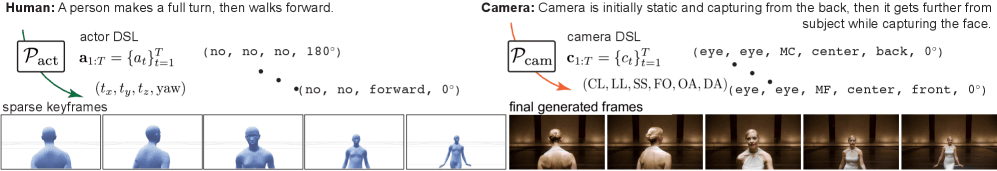
Adobe and university researchers introduced Auteur, a new language-driven framework that uses a domain-specific language (DSL) and LLM-based director to automate human-centric camera framing in generative video. This method enables precise control over shot size and composition by defining camera movement relative to actor pose, suitable for conditioning downstream video generators. Auteur was trained and evaluated on a new dataset of 34K aligned text, human motion, and DSL-annotated camera trajectories.
Auteur directly addresses a core challenge in generative video: achieving intentional, professional-grade camera control that is currently absent in models treating camera motion as a byproduct. By linking camera behavior to semantic framing relative to human subjects, it provides a means to create videos with coherent visual narratives that resonate with professional cinematographic principles. This development moves beyond passive viewpoint generation, enabling creators to author precise cinematic camera paths through natural language. Industry professionals should monitor how this approach influences upcoming generative video platforms and the tools provided for granular control over AI-generated content, particularly for narrative and advertising applications where aesthetic quality and specific framing are critical.
Add StreamingMeme as a preferred source on Google to see more of our streaming news at the top of your Search results.
Add as preferred source